Skip to content
Projects

Projects and case studies

GenAI systems, end-to-end ML platforms, commercial analytics and applied machine learning, each backed by source code, a live demo or a written case study.

14
Projects across GenAI, ML and analytics
5
Live demos you can try in the browser
12
Public repositories with full source code
3
GenAI and NLP systems, including RAG and LLM ranking

Featured

End-to-end systems covering data pipelines, models, testing and reporting
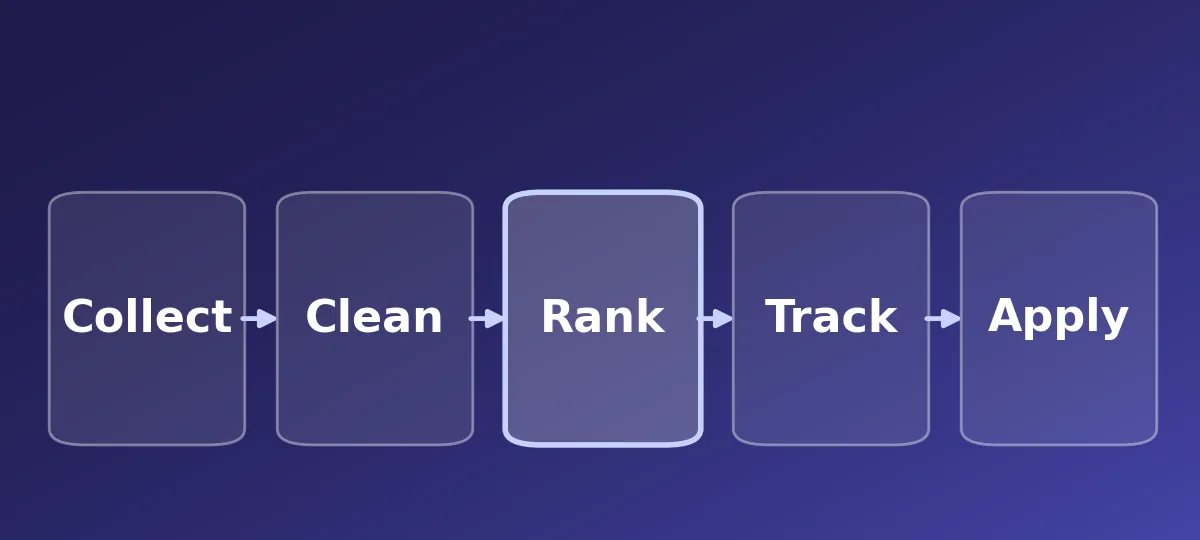
Pipeline diagram: collect, clean, rank, track and applyCase study
GenAI · Multi-LLM system

Multi-LLM GenAI Job-Search Agent

A multi-LLM system that collects 2,000+ live roles a day from 9 ATS APIs and job boards, scores each one against my CV with a three-model LLM-as-a-judge cascade, and assists with applications through a Chrome extension that learns from my edits.

2,000+ roles a day3-model LLM cascade140+ automated tests
PythonTypeScriptSupabaseOpenAI · Gemini · DeepSeekNext.jsChrome MV3
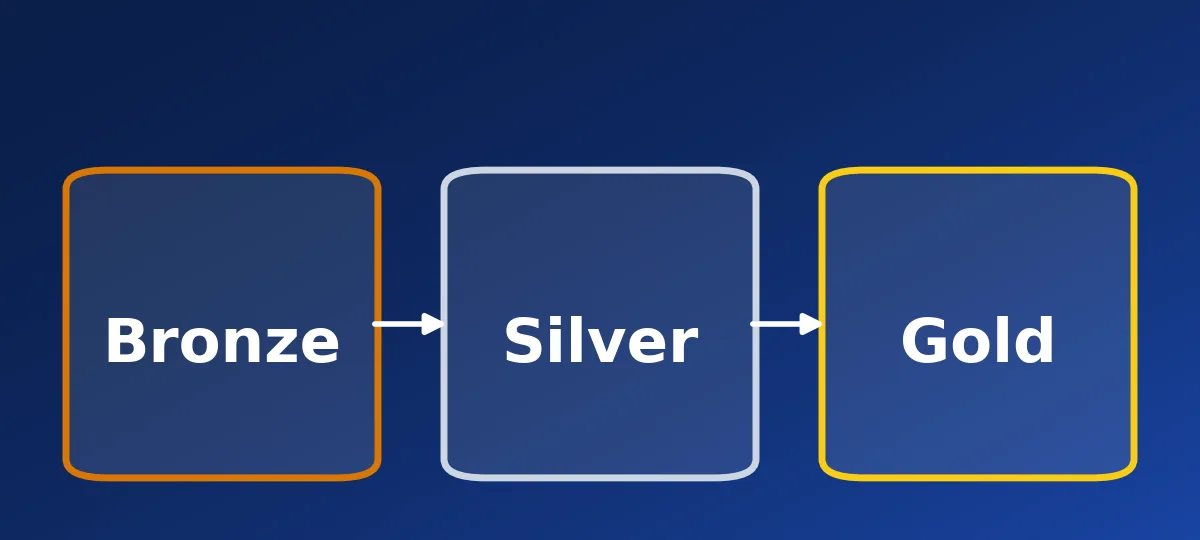
Bronze, silver and gold data layersEnd to end
ML engineering · Insurance

Health Insurance Analytics Platform

An end-to-end platform on PySpark and Delta Lake: bronze, silver and gold layers, star-schema marts, and churn, fraud and high-cost-claim classifiers with MLflow experiment tracking, batch scoring, data-quality monitoring, Docker and CI/CD in GitHub Actions.

3 classification modelsMedallion architectureCI/CD
PySparkDelta LakeMLflowscikit-learnDockerGitHub Actions
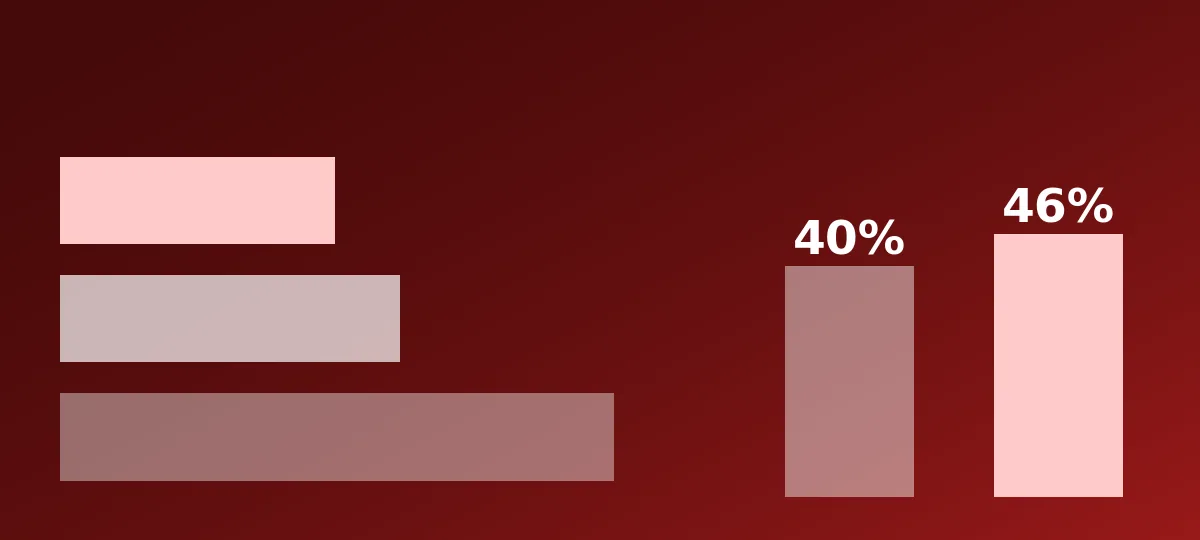
Risk tiers and the simulated recovery rate rising from 40% to 46%Analytics
Customer analytics · Collections

RFM Debt-Recovery Platform

A public version of the collections segmentation approach I delivered at Infosys, on synthetic data: RFM features engineered in SQL with CTEs and window functions, high, medium and low risk tiers, a recovery playbook and an impact simulation, reported in Streamlit.

194,914 accounts tiered+13.9% simulated recovery12 days faster
SQLPythonRFM segmentationStreamlitpytest

MSc academic projects

Coventry University, 2025–2026
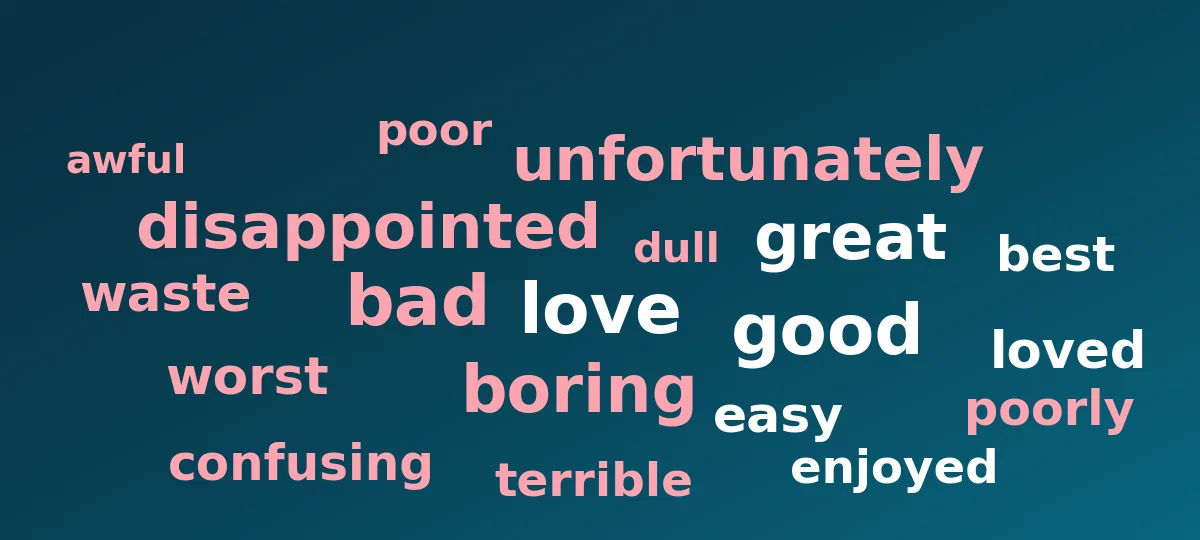
Most frequent positive and negative words in the book reviewsMSc dissertation
NLP · Sentiment analysis

Consumer Review Intelligence

My MSc dissertation as a reproducible pipeline: 10,000 Amazon Books reviews from the Amazon Reviews 2023 dataset, Bag-of-Words and TF-IDF features, tuned SVM, Naive Bayes and Random Forest classifiers, and an analysis of reviews whose star rating contradicts their text.

10,000 reviews6 model and feature pairs
Pythonscikit-learnNLTKVADERTF-IDF
Embedding space with a query and its nearest document chunksMSc
GenAI · Retrieval-augmented generation

RAG Analytics Agent

Question answering over business reports, with every answer traced to its source page. Reports in PDF, Word, Markdown or text are chunked, embedded into a FAISS index and retrieved for a Gemini model, with automated answer evaluation and unit tests across the pipeline.

Page-level citationsAutomated answer evaluation
LangChainFAISSGemini APIStreamlitpytest
Weekly sales baseline with promotional upliftMSc
Commercial analytics · CPG

Strategic Revenue Management & Trade Promotion Optimisation

The pricing and promotion methods I used in industry, rebuilt on synthetic scanner data with known elasticities: log-log demand models for 70 market and product groups, baseline and incremental decomposition, a guardrail-constrained promotion optimiser and an elastic-net marketing mix model.

Median R² 0.99Elasticity error 0.026+13.7% modelled profit
PythonPySparkR · glmnetOR-ToolsDatabricks
Illustration of partitioned dataMSc
Big data · Classification

Big Data Churn Modelling with PySpark

MSc Big Data module coursework: a PySpark workflow that engineers features and trains logistic regression and random forest classifiers for customer churn, with the results presented in Tableau.

PySpark ML pipelineTableau reporting
PySparkSpark MLlibTableau

Applied machine learning

Trained models deployed as web apps and APIs, five with live demos
Churn rate rising with the number of customer service calls LiveDeployed
MLOps · Telecom

Customer Churn Analytics

A random forest churn classifier served through FastAPI, with a web form and a REST scoring endpoint, containerised with Docker and deployed on Azure, with automated tests and CI in GitHub Actions.

Live on AzureREST API
Pythonscikit-learnFastAPIDockerAzure
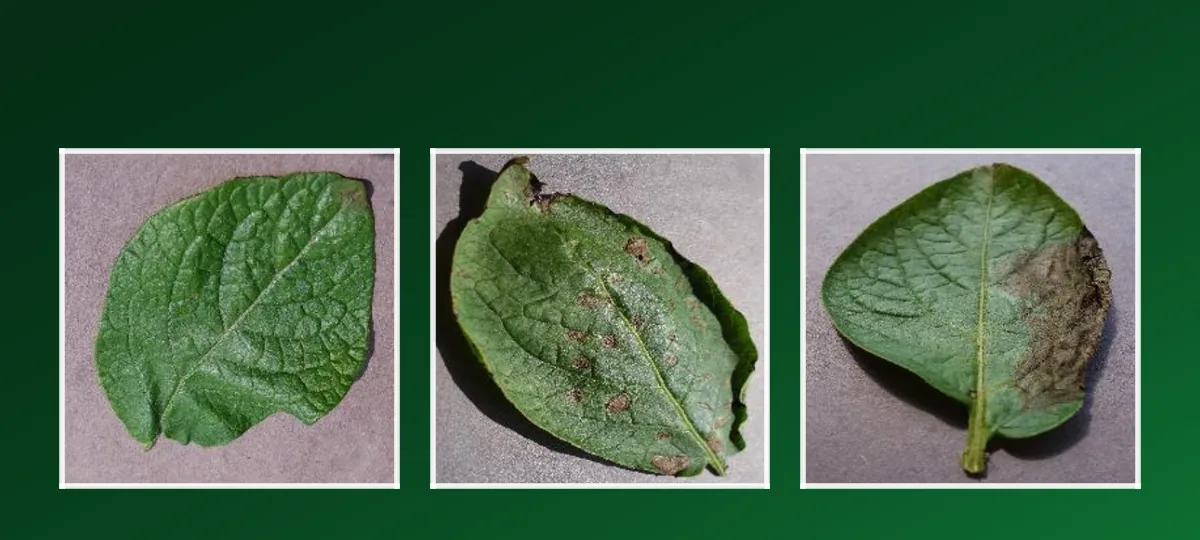
Healthy, early blight and late blight potato leaves LiveDeep learning
Computer vision · Agriculture

Potato Disease Analyser

A TensorFlow convolutional neural network trained on 2,152 PlantVillage images to classify potato leaves as early blight, late blight or healthy, served through FastAPI, a Streamlit app and a command-line tool.

95% test accuracy3 disease classes
TensorFlowCNNFastAPIStreamlit
Applicant income against loan amount LiveClassification
Finance · Credit risk

Loan Approval Analyser

A random forest classifier that assesses loan eligibility from applicant financial and demographic features, with a live debt-to-income calculation and confidence scores in a Streamlit app.

82% test accuracyConfidence scoring
Pythonscikit-learnStreamlit
House value against the average number of rooms LiveRegression
Real estate · Regression

House Pricing Analyser

A random forest regression on 490 Boston housing records with engineered interaction features, a reproducible training script, persisted model artefacts and tracked metrics, served through Streamlit.

R² 0.87RMSE 2.58
Pythonscikit-learnFeature engineeringStreamlit
Tumour mean radius against mean texture LiveClassification
Healthcare · Classification

Breast Cancer Analyser

A scaled logistic regression pipeline on the Wisconsin Diagnostic dataset that classifies tumours as malignant or benign, evaluated on accuracy, precision, recall, F1 and ROC AUC, with a Streamlit app and unit tests.

ROC AUC 0.996
Pythonscikit-learnStreamlitpytest
Gemstone price rising with carat weightRegression
Pricing · Regression

Gemstone Price Analyser

A modular training and inference pipeline that estimates gemstone prices from carat, cut, colour, clarity and dimensions. Five tuned ensemble models, including XGBoost and CatBoost, are compared and the best on test R² is served through a Flask API and a Streamlit front end.

5 tuned ensemble modelsAutomated model selection
scikit-learnXGBoostCatBoostFlaskStreamlit
Reading score against maths scoreRegression
Education · Regression

Student Performance Analyser

A modular regression pipeline that estimates a student's maths score from demographic and academic indicators. Nine regressors are benchmarked, the best is persisted, and scores are served through a Flask app.

9 regressors benchmarked
Pythonscikit-learnFlask